
The creation of digital media used to be a massive grind. Just a few years ago, wanting high-quality visuals meant a lot of work. It meant needing deep software expertise, a physical photography studio, and hours of tedious editing.
However, today Generative AI in Visual Content Creation has completely flipped that workflow on its head.
Anyone can type a simple text prompt or upload a rough reference. Then they can watch a neural network spit out a high-resolution graphic in seconds.
What started as a weird internet novelty has quickly turned into an essential tool for professional designers.
This massive shift is happening because of huge breakthroughs in deep learning architectures. That is especially true with diffusion models and transformers that finally bridge the gap between a random idea in your head and a finished asset.
Understanding The Engine: How Generative Image Models Function
To appreciate the capabilities of modern media tools, it helps to look under the hood at the underlying computer vision and deep learning paradigms.
Early automated image tools relied primarily on rule-based algorithmic filters or spatial manipulation.
Today’s generative workflows leverage deep neural networks trained on vast, diverse datasets of paired visual and textual information.
Text-To-Image Synthesis And Latent Diffusion
Latent space representation is placed at the core of modern image generation.
When you type in a prompt, a text encoder translates your natural language into a mathematical roadmap.
A diffusion network then steps in, starting with a completely random field of digital noise. Gradually, it scrapes it away until a clean image emerges that matches your exact description.
Multi-Turn Iteration And Spatial Consistency
For a long time, the biggest headache with this technology was control.
Early models could make a cool single image. However, if you asked them to modify one tiny detail, the entire scene would collapse into a totally different style.
For instance, when you ask to swap a background while keeping the main character the same, the issue may occur.
Conversely, recent updates have fixed this hurdle.
Creators can now do the following effortlessly without any headaches:
- Pinpoint localized edits
- Jump back and forth with the AI in a conversation to tweak specific layers
- Make precise adjustments without ruining the rest of the picture
Architectural Breakthroughs: The Rise Of Multi-Modal Intelligence
The real turning point happened when these systems stopped relying purely on text inputs.
Modern visual synthesis engines can now evaluate spatial sketches, reference photos, depth maps, and layout guides all at once to build exactly what you want.
Unifying these different inputs gives designers a massive amount of structural control over the final image.
In-Image Typography And Text Rendering
Early image models were notorious for turning words into unreadable, alien gibberish.
Newer architectures fix this by integrating advanced sequence transformers.
Now, finally, it allows the system to render crisp, perfectly legible text right onto banners, posters, and product concepts.
Identity And Character Preservation
Thanks to smarter embedding alignment, models can now extract specific facial features or clothing details from a reference photo.
It can then keep that exact character looking identical across entirely different lighting setups and environmental backgrounds.
Reference-Guided Composition
Instead of forcing the AI to guess where things should go based on words alone, you can just feed it a rough layout sketch.
Moreover, the system reads your lines to lock in the perfect camera angles, object placement, and perspective scales.
Industry Applications Across Creative Workflows
The true value of these visual networks isn’t just that they look cool.
Instead, it is how much they compress the time between brainstorming and rendering.
Because they cut down production timelines so aggressively, they are popping up across almost every digital industry.
Marketing And Social Media
Marketing teams often require high volumes of customized visual content across multiple display formats.
Generative workflows enable rapid prototyping of promotional banners, seasonal campaign concepts, and social graphics tailored to platform-specific aspect ratios.
Product Prototyping And Packaging Design
Before spending a fortune on physical manufacturing or slow, costly 3D renders, industrial and graphic designers use artificial intelligence.
This allows them to quickly visualize product packaging variations, merchandise styles, and spatial display setups.
Digital Storytelling And Concept Art
Indie game developers, graphic novelists, and filmmakers leverage AI synthesis to convert story beats into detailed visual panels, storyboards, and environment designs.
This accelerates mood boarding and concept approval long before pre-production begins.
Integrating Generation With End-To-End Asset Editing
An AI graphic on its own rarely crosses the finish line for a professional campaign.
High-stakes publishing usually requires extra tweaks like precise cropping, color grading, or stripping out a background to fit a brand’s specific style guide.
Modern content creation platforms bring these steps together into unified ecosystems.
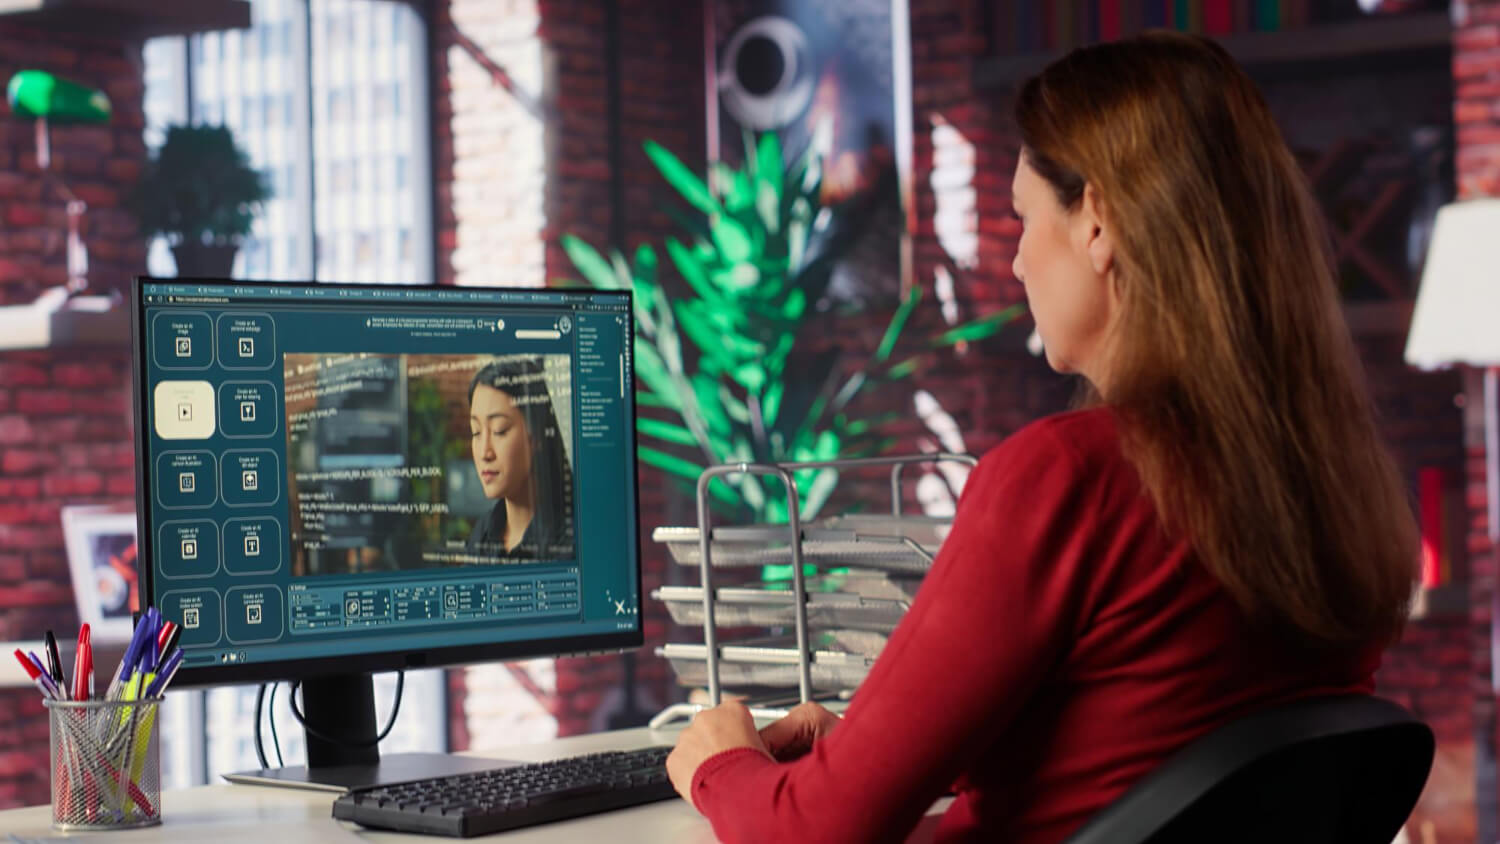
For instance, creators can generate base concepts using a versatile AI image generator to quickly convert text prompts into rich canvas assets.
From there, assets can move into non-destructive raster editing, vector adjustments, or even video animation pipelines without leaving the web browser or desktop editor.
Specialized models are gaining serious traction across these creative platforms, giving users unprecedented control.
Tapping into tools like the GPT Image 2.5 AI image generator allows users to leverage advanced multi-modal editing.
Additionally, you are able to:
- transform rough hand-drawn sketches into polished vectors
- issue targeted text instructions
Thus, as a creator, you can modify specific image regions while maintaining full structural fidelity.
Best Practices for Prompt Crafting and Visual Control
Getting predictable results out of a generative model comes down to how you talk to it.
If you treat the prompt box like a structured creative brief for a human artist, your visual outputs will come out significantly cleaner.
Establish the Core Subject First
Clearly name your main subject, character, or focal element right at the start before you worry about adding any ambient details.
Define Environmental Mechanics
Specify the exact setting and the camera perspective.
For instance, a wide-angle, eye-level shot or a macro close-up, and atmospheric lighting, like natural golden-hour sun or moody studio rim lights.
Specify Material Textures and Styles
Avoid using lazy, empty buzzwords like hyperrealistic.
Instead, tell the model exactly what style you want, whether that is gritty 35mm film grain, thick oil paint textures, or flat vector lines.
Iterate Incrementally
Don’t try to change everything at once.
Change one variable at a time across your generation runs so you can guide the image to perfection without confusing the system.
Ethical Considerations And The Future Of Synthetic Media
As artificial intelligence integrates deeper into professional workflows, the creative community is dealing with some heavy technical and ethical growing pains.
Data Attribution And Intellectual Property
The biggest conversation right now is around data attribution and copyright.
Tech companies and artist groups are actively pushing for clearer data licensing models.
On the other hand, it is reliable opt-out systems for creators and digital watermarking to protect original work.
Transparency And Provenance
Now that AI images are becoming indistinguishable from real photography, the industry is adopting new metadata standards like C2PA.
Consequently, this builds a digital paper trail directly into the file.
This allows audiences to easily see whether an image was captured on a real camera or generated by a computer. Moreover, this is crucial for fighting misinformation.
The Horizon Of Digital Content Creation
Ultimately, these tools aren’t here to replace human artists. They act as force multipliers that handle the repetitive, time-consuming rendering work.
Thus, designers can focus on the big picture, like storytelling, concept direction, and creative vision.
As the technology moves toward real-time editing and seamless video generation, the line between static art and dynamic storytelling is going to vanish completely.
Learning to use these tools right now gives modern creators the speed and flexibility they need to thrive in a fast-moving digital landscape.